Local LLM Inference for Enterprise AI Projects
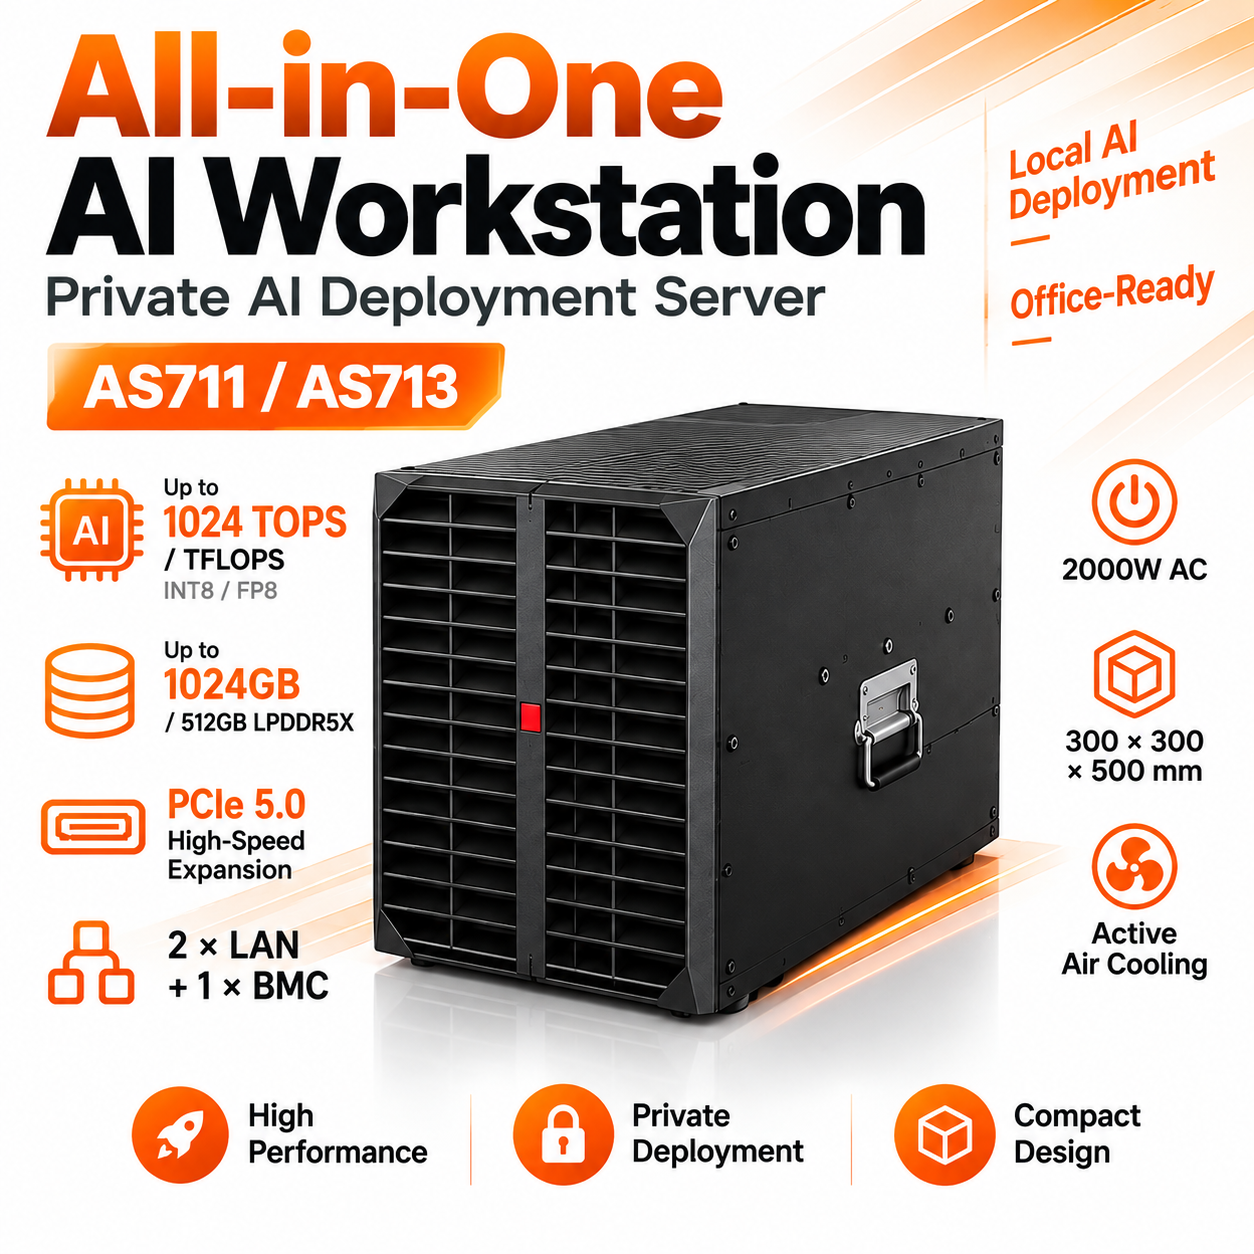
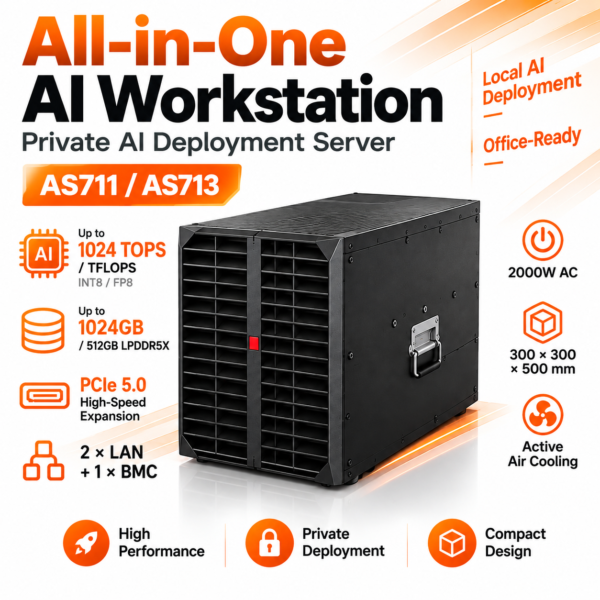
The AS711 and AS713 are high-memory AI inference servers designed for running large language models on local infrastructure. They are intended for enterprise AI deployments, software integration projects and organizations evaluating dedicated hardware for private AI applications.
The AS713 provides 512GB of LPDDR5X accelerator memory. The AS711 increases this to 1024GB and includes more system RAM and an additional data SSD.
Both models use a compact tower enclosure with active air cooling. Ubuntu and Kylin Linux are listed as supported operating systems.
AS711 vs AS713: Which Configuration Should You Choose?
| 사양 |
AS711 |
AS713 |
| Product positioning |
Higher-memory configuration for larger model requirements |
Standard configuration for mainstream inference deployments |
| AI accelerator memory |
1024GB LPDDR5X |
512GB LPDDR5X |
| System RAM |
256GB DDR5, 4 × 64GB |
128GB DDR5, 2 × 64GB |
| System SSD |
1 × 512GB M.2 NVMe |
1 × 512GB M.2 NVMe |
| Data SSDs |
2 × 3.84TB U.2 NVMe |
1 × 3.84TB U.2 NVMe |
| Operating system options |
Ubuntu / Kylin Linux |
Ubuntu / Kylin Linux |
Choose AS713 when its 512GB accelerator memory configuration meets the requirements of your selected model and workload.
Consider AS711 when your project requires additional accelerator memory, system RAM or local storage. Model compatibility and usable performance should be evaluated separately from memory capacity.
Hardware Specifications
The following platform specifications are listed in the supplier’s AS71X product introduction v1.2.0. Confirm the selected configuration in your quotation.
| Item |
Published Specification |
| CPU |
Chinese-developed processor, 2.8GHz, 16 cores / 32 threads |
| INT8 compute |
1024 TOPS |
| FP8 compute |
1024 TFLOPS |
| FP16 / BF16 compute |
512 TFLOPS |
| TF32 compute |
256 TFLOPS |
| FP32 compute |
64 TFLOPS |
| Accelerator memory type |
LPDDR5X, 8533 Mbps |
| Memory bandwidth |
2184 GB/s |
| Host interface |
PCIe Gen5 ×16 |
| Expansion slots |
2 × PCIe 5.0 ×16 |
| Network ports |
2 × Gigabit Ethernet |
| Management connection |
1 × BMC management network port |
| External interfaces |
1 × USB Type-C, 1 × HDMI, 2 × USB 3.0 |
| Storage connectivity |
3 × M.2 SSD positions and 4 × U.2 2.5-inch SSD positions |
| Power supply rating |
2000W AC |
| Supplier-stated typical power consumption |
Below 1000W |
| Supplier-stated peak power consumption |
1300W |
| Cooling |
Active air cooling |
| Operating temperature |
0°C to 40°C |
| 치수 |
300 mm W × 300 mm H × 500 mm D |
Compute figures describe the published hardware specifications. Application throughput depends on the model, precision, context length, software and workload.
The 2000W figure is the power supply rating, not the stated typical operating consumption.
Published LLM Inference Benchmarks
The supplier reports the following results using FP8 precision and the vLLM bench tool.
| 모델 |
Reported Context |
Batch |
Reported Decode Throughput |
| Qwen3.5-35B |
8K |
4 |
120 tokens/s |
| Qwen3.5-35B |
8K |
32 |
520 tokens/s |
| Qwen3.5-122B |
8K |
1 |
38 tokens/s |
| Qwen3.5-122B |
8K |
8 |
195 tokens/s |
| Qwen3.5-397B |
8K |
1 |
29 tokens/s |
| Qwen3.5-397B |
8K |
8 |
125 tokens/s |
| MiniMax-M2.7 |
8K |
1 |
30 tokens/s |
| MiniMax-M2.7 |
8K |
8 |
118 tokens/s |
How to interpret these results: The 520 tokens/s result applies to Qwen3.5-35B at batch 32 and the reported 8K context setting. It is a batched throughput result, not a guaranteed generation speed for each user.
These are supplier-reported results, not independent PunkHash benchmarks. The source does not identify the exact AS711 or AS713 configuration used for each test, the software build, or the complete input and output lengths. Request a workload-specific evaluation before using these figures for capacity planning.
Source: AS71X Product Introduction v1.2.0, August 2026, benchmark section.
Model Compatibility and Adaptation Status
The supplier’s documentation distinguishes completed adaptation, ongoing optimization and future work.
| Model Family |
Status Described in the Product Documentation |
| MiniMax |
Adaptation reported as completed; MiniMax-M2.7 benchmark results are provided |
| Qwen3.5 |
Benchmarks provided for 35B, 122B and 397B; performance optimization is ongoing |
| GLM5 family |
Demonstrations referenced; specific GLM5.1 / GLM5.2 support requires confirmation |
| DeepSeek V4-Flash |
Listed in the future adaptation roadmap |
The documentation also states support for a 32K context with MiniMax-M2.7. The published benchmark table above uses an 8K context setting.
Model versions and software packages evolve. Confirm the exact model checkpoint, precision and deployment package for your order.
Practical Deployment Scenarios
Enterprise Knowledge Assistants
Evaluate a local language model as part of an internal knowledge assistant. The complete application may also require document ingestion, retrieval software, permissions and a user interface.
Tender and Proposal Workflows
With a suitable application layer, local inference can support tender-document search, summarization and drafting workflows. The supplier lists tender-assistant solutions among its target applications.
Financial, Publishing and Healthcare Applications
The supplier identifies banking, securities, publishing and healthcare as target sectors for partner-delivered solutions. Application-specific integration, access controls and acceptance testing should be included in the project scope.
AI Software and System Integration
ISVs and system integrators can evaluate the AS711 / AS713 as the inference hardware within a customer solution. The supplier describes partner cooperation covering model adaptation, delivery and ongoing operations.
Industry applications and software services are project-dependent and are not automatically included with the hardware.
Remote Evaluation Before Deployment
Remote testing can be arranged through:
- Remote desktop access.
- HTTP API access.
For a useful evaluation, provide your target model, intended context length, expected concurrent requests and representative tasks.
Agree on the test configuration and assess response latency, output throughput, stability and integration requirements before selecting the final system.
Installation and Delivery Planning
Check the installation location against the stated 0°C to 40°C operating range, power requirements and ventilation needs.
Although the enclosure supports deployment outside a traditional rack format, office suitability also depends on heat removal and noise expectations. The product documentation does not provide an acoustic rating.
Before ordering, confirm:
- Exact server model and component configuration.
- Processor and AI accelerator identification.
- Operating system and included software versions.
- Model adaptation and application installation scope.
- Required network connectivity.
- Warranty, remote support and repair arrangements.
- Delivery destination and lead time.
Frequently Asked Questions
What is the main difference between AS711 and AS713?
AS711 has 1024GB of LPDDR5X accelerator memory, 256GB of DDR5 system RAM and two 3.84TB data SSDs. AS713 has 512GB of accelerator memory, 128GB of system RAM and one 3.84TB data SSD.
Is the advertised 1024GB capacity system RAM?
No. The documentation identifies 1024GB as the AS711 accelerator memory capacity. Its separate DDR5 system RAM is 256GB.
Can the server run Qwen and MiniMax models?
The supplier publishes FP8 benchmarks for Qwen3.5-35B, Qwen3.5-122B, Qwen3.5-397B and MiniMax-M2.7. Confirm the exact model version and software package for your selected configuration.
Does 520 tokens/s mean every user receives that speed?
No. The published result is for Qwen3.5-35B at batch 32 with a reported 8K context setting. It should not be treated as a per-user speed guarantee.
Does the server continuously consume 2000W?
No. The documentation lists a 2000W AC power supply, typical consumption below 1000W and peak consumption of 1300W. Actual consumption varies with the configuration and workload.
Can it run without an internet connection?
Local deployment does not automatically mean fully offline operation. Confirm model availability, software licensing, installation dependencies and external integrations if your project requires a disconnected environment.
Are enterprise AI applications included?
Application software, model adaptation, installation and operational support depend on the project package. Confirm the included deliverables in the quotation.
Can I test the system remotely?
The supplier offers evaluation through remote desktop and HTTP API access. Contact PunkHash to discuss test availability and your workload requirements.
Request a Configuration or Remote Test
Tell PunkHash:
- Which model or application you want to run.
- Your expected concurrent users or requests.
- Your context-length and response-time requirements.
- Required quantity and delivery country.
Request an AS711 / AS713 configuration, quotation or remote evaluation for your project.


상품평
필터 지우기아직 상품평이 없습니다.